You get the code,
Claude keeps the knowledge.
Recently, I've spent a lot of hours building with Claude Code. At some point the waiting started to bother me: what am I actually doing with those minutes? Nothing useful. And everything the session worked out went back to the agent, not to me. That seemed backwards.
Download VibeIQ Mac App
- macOS on Apple Silicon
- Menu bar app
Observation log
Prompt, wait, check back. About 8 minutes each time, 10 times a day. Too small to complain about, so nobody does.
- 1.I'd prompt, go read something else, and come back knowing nothing new about my own project.
- 2.I merged work I couldn't have explained to anyone in a hallway.
- 3.Someone asked why a dependency was there. An agent had decided, in a session I half-watched.
- 4.I watched a non-engineer ship something real with no idea how any of it worked.
Do you have this problem?
Who else has it?
I asked around before building anything. 3 groups, because I thought the same gap would look different depending on who had it. It did. Most people I spoke to said, before I suggested anything, that they would check Slack or email.
People building with agents who don't read code
Founders, operators, marketers. Not worried about code quality. Worried about being asked a question about their own product and having no answer.
Engineering managers
On the hook for a growing share of code nobody on the team wrote by hand. Reviews getting shallower as volume went up, and they knew it.
Founders I know
The blunt version. Velocity up, confidence down, and no longer sure whether the codebase was an asset or a liability.
An estimate. It uses OpenAI's June 2026 figure of more than 5 million weekly Codex users and assumes each waits 8 minutes, 10 times a day. Anthropic has not published a Claude Code count.
Scorecard
Dead time while an agent works, and the knowledge gap it leaves. Six criteria, 1 to 5 each. A 1 on Acute or Reach kills a candidate, whatever else it scores.
- 3/5
Acute
Too small to complain about, so nobody does. The alternative isn't nothing: most people said straight away they would check Slack or email. The cost is real (I merged work I couldn't have explained in a hallway), but it is tolerated, not suffered.
- 5/5
Frequency
About 8 minutes each time, 10 times a day. In Stack Overflow's April 2026 survey (n=1,100), 37% of developers use AI agents at work daily and 13% weekly.
Source: Stack Overflow
- 4/5
Reach
OpenAI said in June 2026 that Codex has more than 5 million weekly active users. Anthropic hasn't published a Claude Code count; in February it said weekly users had doubled since 1 January.
Source: OpenAI, via Constellation Research, Anthropic, via Simon Willison
- 3/5
Current spend
People spend the wait on Slack and email. I couldn't name a paid tool people use to understand what an agent did, so this scores in the middle.
- 5/5
Why now
Claude Code writes a transcript of every session, which is what makes a fix possible. Agent use at work went from 31% in 2025 to 59% in April 2026.
Source: Stack Overflow
- 5/5
Buildable in a week
Shipped inside the week.
Total 25 of 30
- Afterwards, not scored: a diagram of my project, so I understand it as a system and decide with more information. I didn't go deep on it. I built a rough version inside VibeIQ.
Kills
Nothing killed this week. One candidate scored, one built. That will not always be the case.
The pick
Dead time, 25 of 30. It passed with soft Acute and Current spend scores. I built it anyway because Frequency and Why now were the strongest, and the fix needed no setup, no new credentials and no new cost. I wrote the constraints down before building, so they were a test I could fail rather than an argument for what I'd already made.
Zero setup
If it needs configuring, it won't be there during an 8-minute wait.
No new security exposure
It can't ask for my source, my repo, or another set of credentials.
No new cost
I already pay for Claude. I'm not paying again to understand what it did.
Ask the agent to explain what it did
Fails Zero setupI have to remember, every time. And it explains the diff, not the decision.
A web dashboard
Fails No new security exposureSession detail leaves the machine, and it's another tab I'd have to remember to open.
An editor extension
Fails Zero setupInstall it per editor, and it misses everyone running the agent in a terminal.
A daily email or Slack digest
Fails No new security exposurePipes project detail to a third party, and arrives long after the moment has passed.
What's left: a Mac menu bar app
- Zero setup
- Claude Code already writes a transcript of every session. It reads that. Nothing to install into your tools, nothing to configure.
- No new security exposure
- It never reads your source. No repo access, no new credentials, and nothing leaves the Mac unless you switch that on, apart from anonymous usage counts you can turn off.
- No new cost
- Lessons are written on the Claude plan you already pay for.
What did I build?
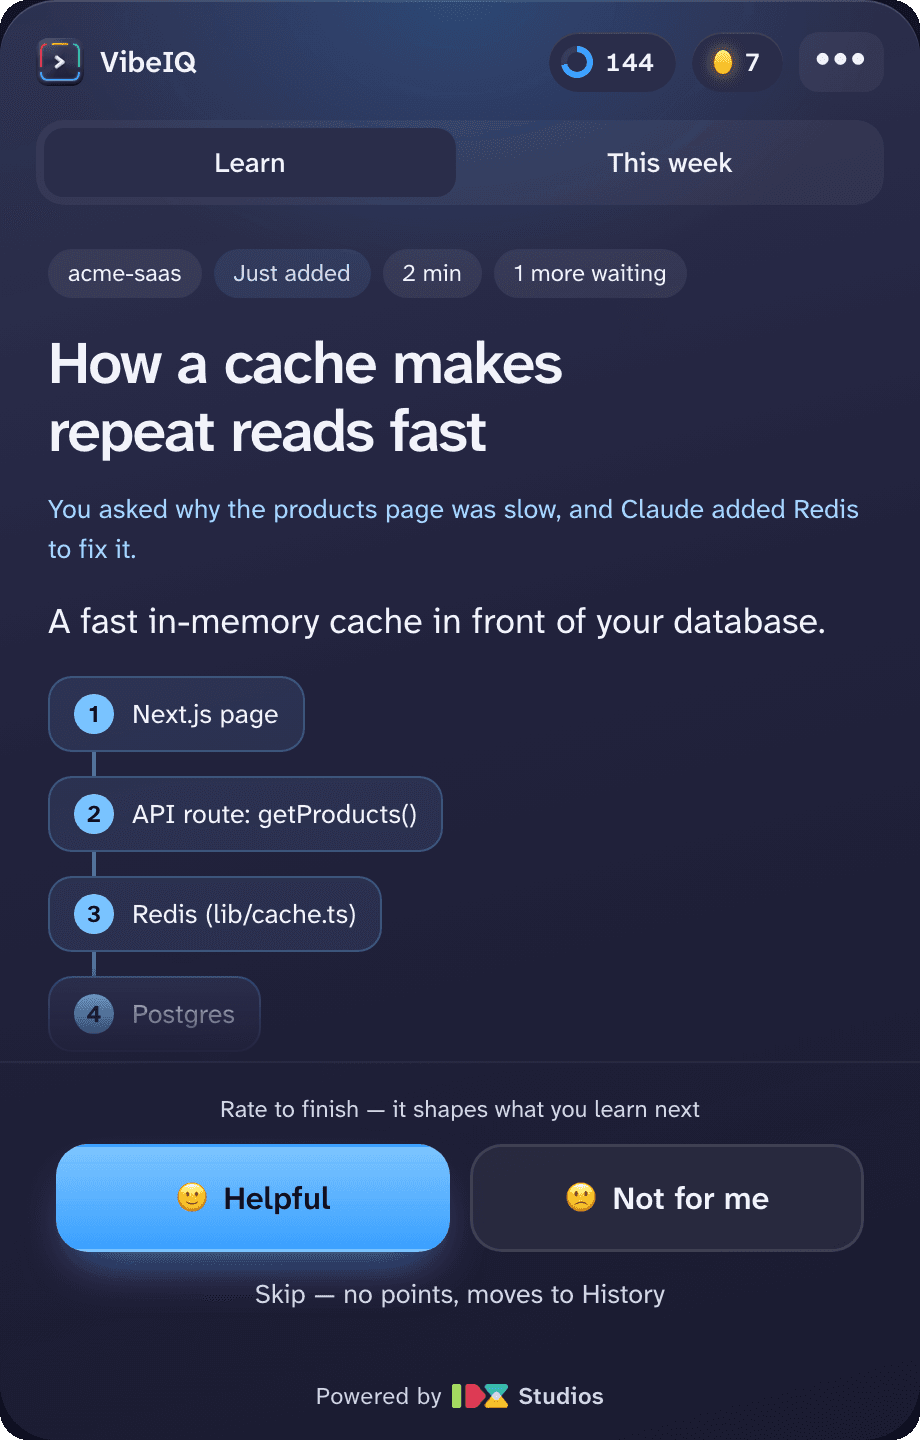
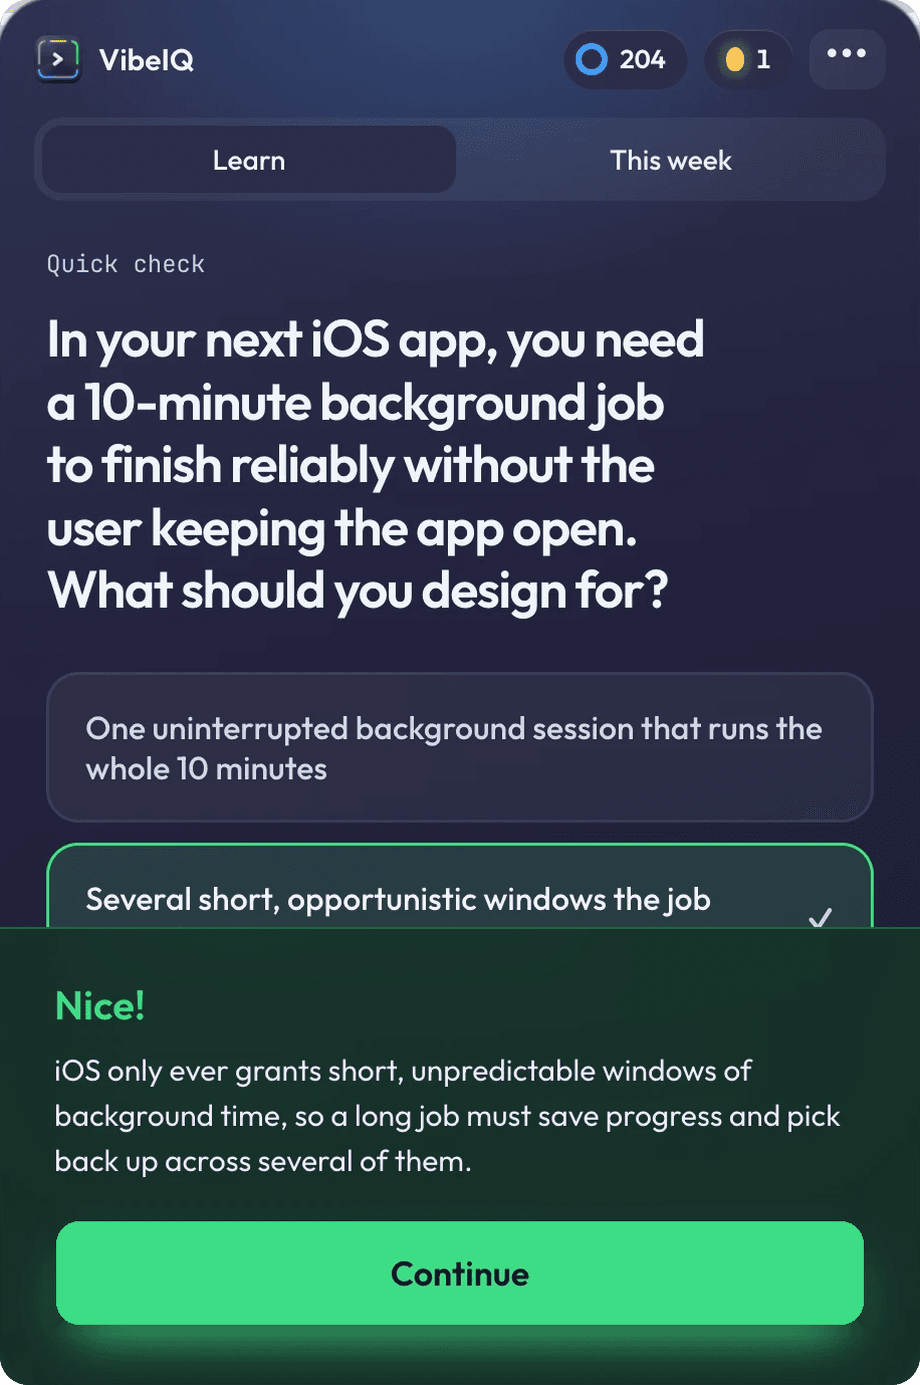
VibeIQ is a Mac menu bar app, like Duolingo for your Claude Code projects. While the agent works it teaches you one thing about what is happening in your own repo, with a picture, a quick check and something to try next time. It reads Claude Code's own session transcript and never your source files, and lessons are written through your own Claude account.
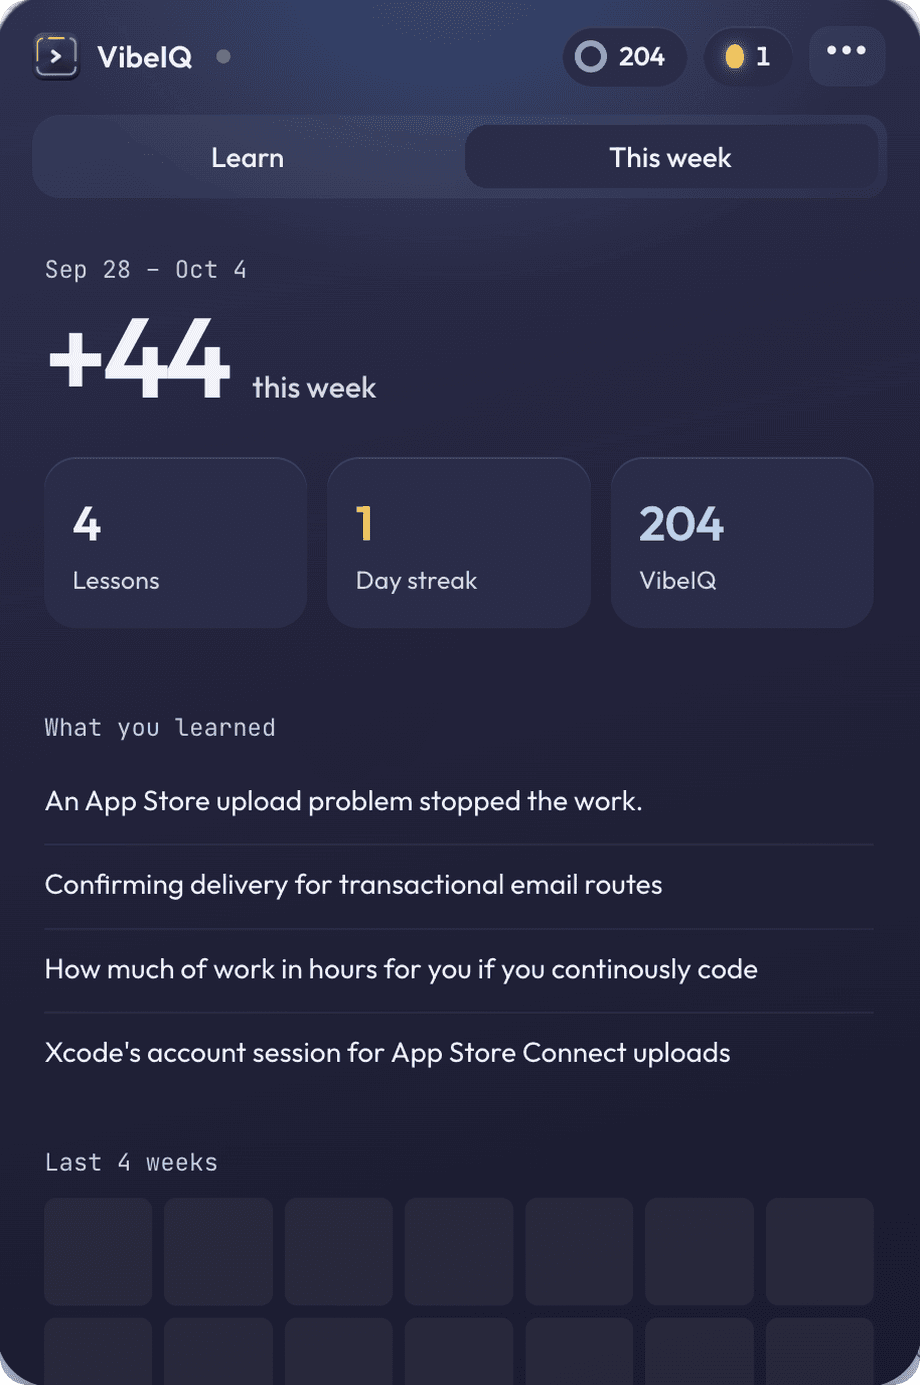
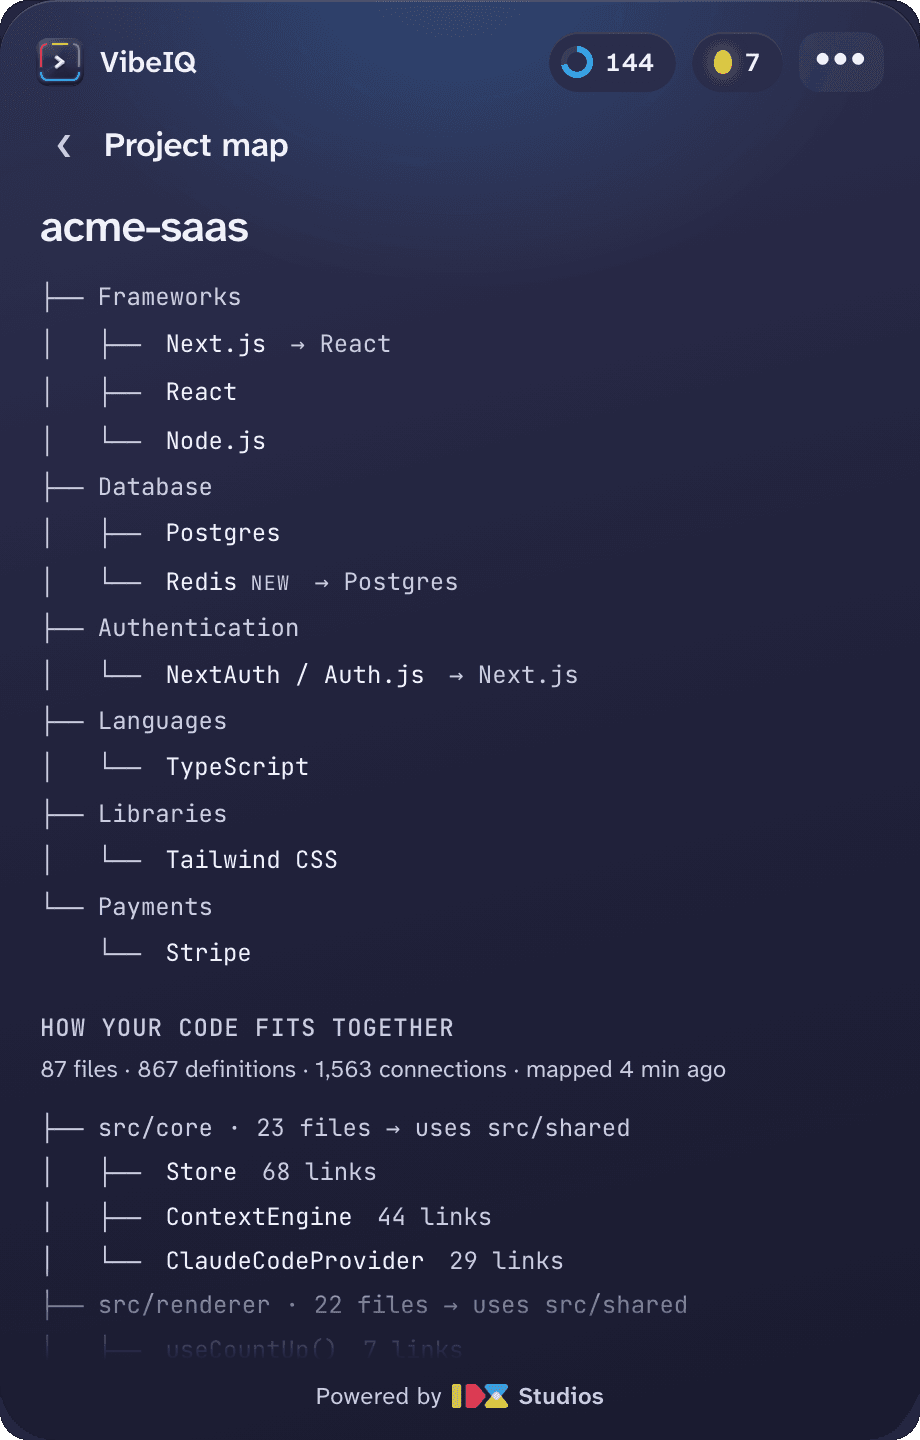
Signals
- Votes
- The two votes on this page: whether you have the problem, and whether it was worth building.
- 30-day follow-up, by 22 October 2026
- Downloads, weekly active users, one user quote, and whether I still use it.
- 90-day follow-up, by 21 December 2026
- The same four, and whether the numbers moved.
Was it worth it?
Yes. The problem is worth solving. It scored 25 of 30, and the weak points, Acute and Current spend, are weak for a reason I can name: the wait is tolerated, and nobody I know pays to fill it. Tolerated problems are slow to convert. What I don't know yet is whether a menu bar app that teaches you during the wait is the fix. The download number answers that, and I'll report it at 30 and 90 days whether it is good or bad.
Is It Worth Solving?
Every week I log problems, score them against the same six criteria, kill the weak ones and build the winner. Then I report whether it was worth it, at 30 and 90 days. Sometimes the answer is no.
Want this run on your business?
Every week I log problems, score them against the same six criteria, kill the weak ones and build the winner. I do the same for companies. You bring the observation log from your customers, your support queue and your team. I score it, kill what fails, and build the strongest one with you.
hello@idxstudioz.com, subject “Run the method.”